Repomix
Packs a whole repository into one AI-friendly file, ready to feed to a model.
Website captured Oct 19
Fit more signal into fewer tokens: compaction, summarization, token-efficient formats, repo packers, caching.
13 listed entries
Packs a whole repository into one AI-friendly file, ready to feed to a model.
Website captured Oct 19
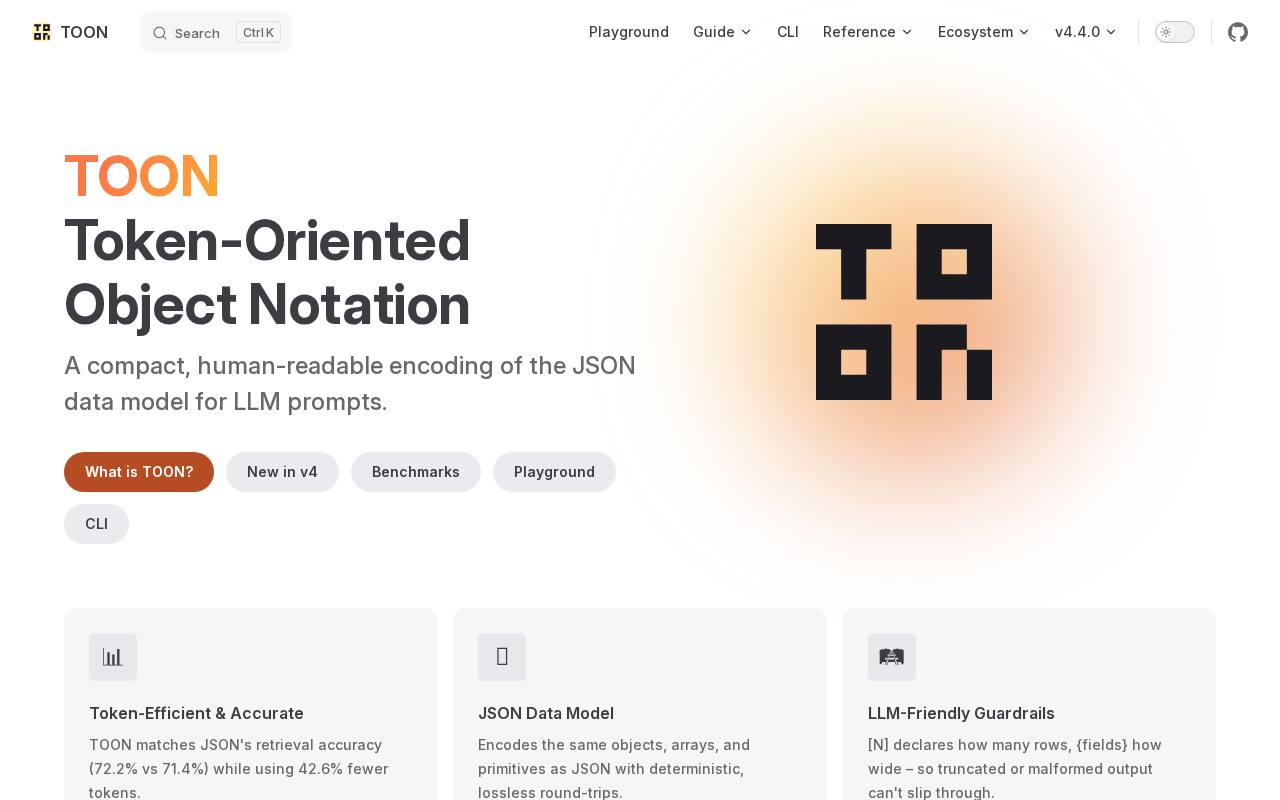

Token-Oriented Object Notation: a compact, human-readable encoding of JSON for LLM prompts.
Website captured Oct 19
Fast BPE tokenizer for OpenAI models: count tokens before they hit the context window.
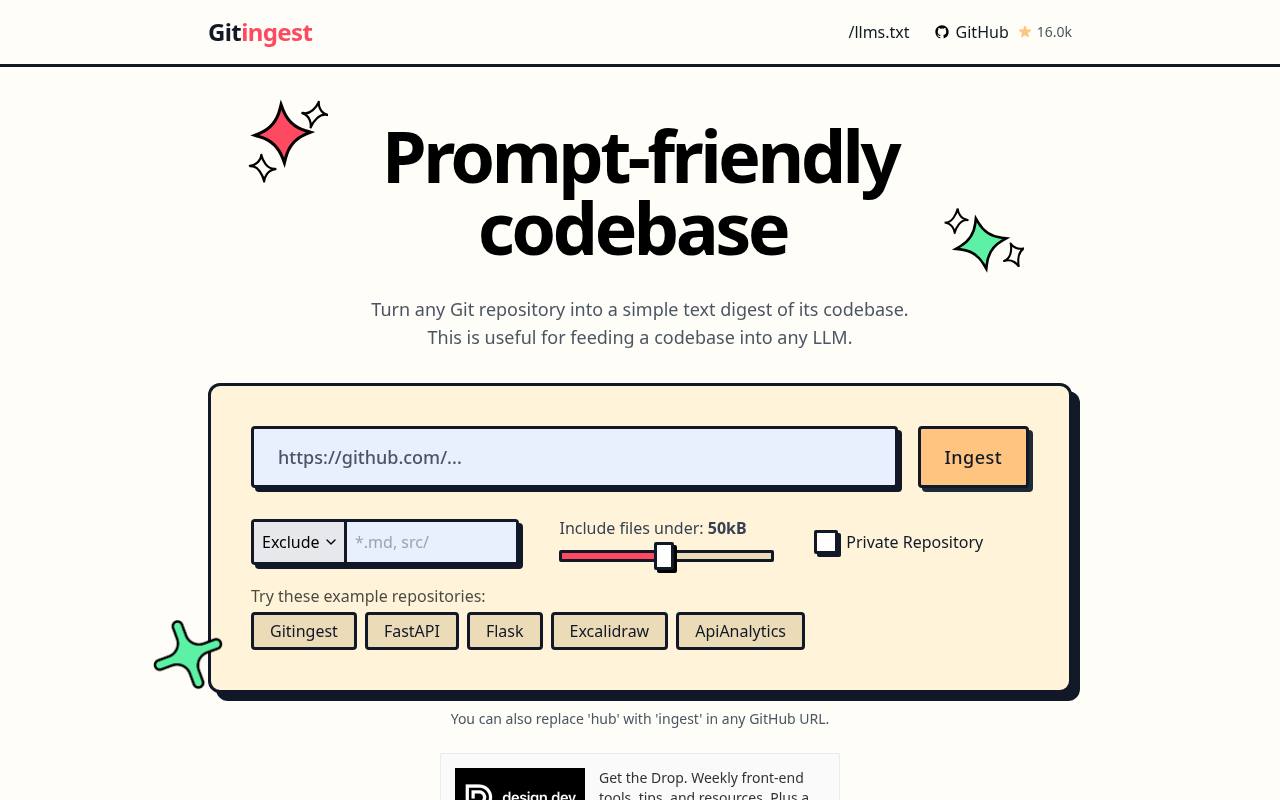
Turns any GitHub repo into a prompt-friendly text digest (swap 'hub' for 'ingest' in the URL).
Website captured Oct 19

CLI that converts a codebase into one prompt with a source tree, templates and token counting.
Website captured Oct 19
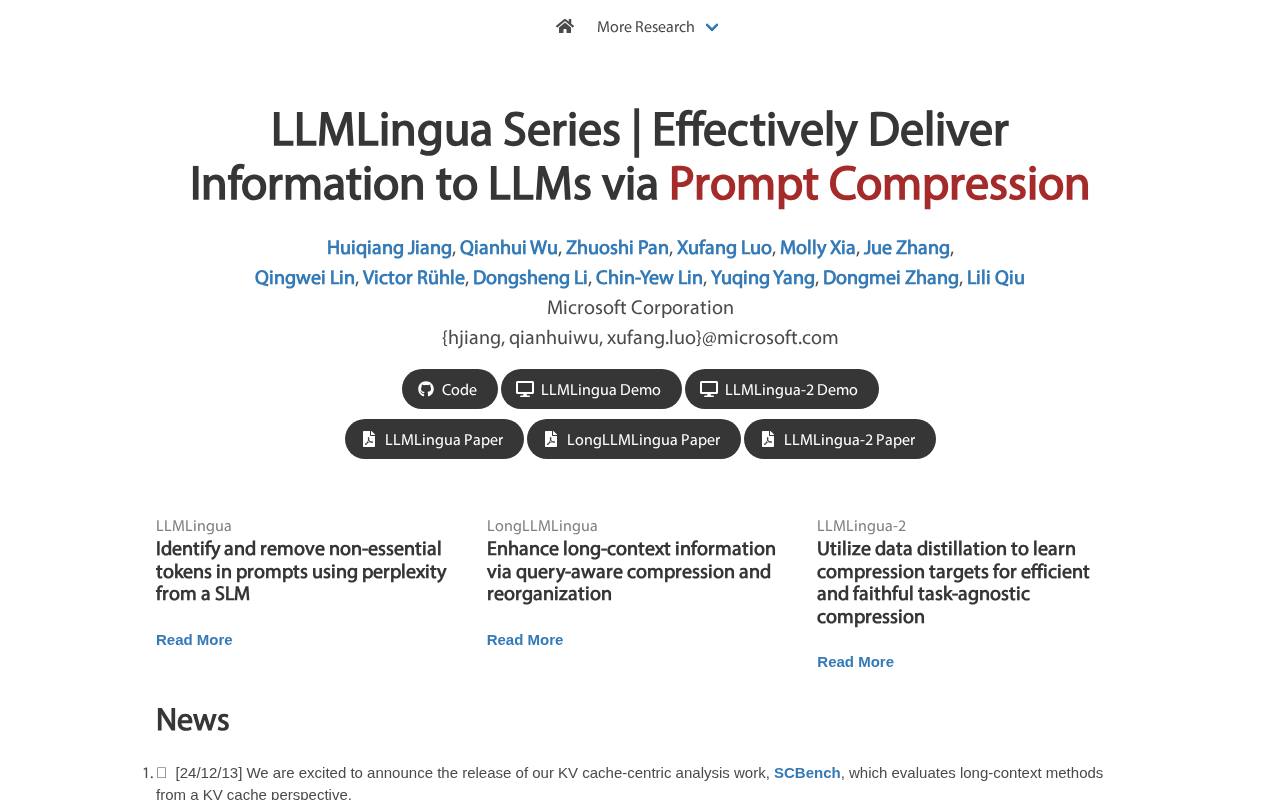
Microsoft's prompt-compression method: drops low-information tokens; the repo reports up to 20x compression.
Website captured Oct 19
The finite attention an LLM spends across its context; every new token draws it down, so context must be curated.
When a conversation nears the window limit, summarize it and restart a fresh window with the summary.
Automatically clearing stale tool calls and results from the context as it nears its limit (a Claude Developer Platform feature).
The share of prompt tokens served from the model's key-value cache; higher means lower latency and cost.
Keep the prompt prefix stable and the context append-only so cached tokens get reused.
Mark the stable prefix (system prompt, tools, reference docs) for caching so repeated calls reuse it.
Drop old tool results from the history once they've been used: the lightest form of compaction.