Retrieve
Pull the right outside knowledge into context, just in time: search, RAG, embeddings, rerankers, docs and code fetchers.
30 tools
- +26
109 curated tools and processes, grouped by the six jobs of context engineering. Every number links to its source.
Pull the right outside knowledge into context, just in time: search, RAG, embeddings, rerankers, docs and code fetchers.

Keep what matters outside the window across turns and sessions, and bring it back when needed.


Give agents actions and live data through tools: MCP servers, SDKs, registries and tool design.
Fit more signal into fewer tokens: compaction, summarization, token-efficient formats, repo packers, caching.

Split work across agents with clean, isolated contexts: agent frameworks, sub-agents, handoffs, workflows.

See what went into the context and whether it worked: tracing, evals, regression tests, token and cost tracking.

Pull the right outside knowledge into context, just in time: search, RAG, embeddings, rerankers, docs and code fetchers.
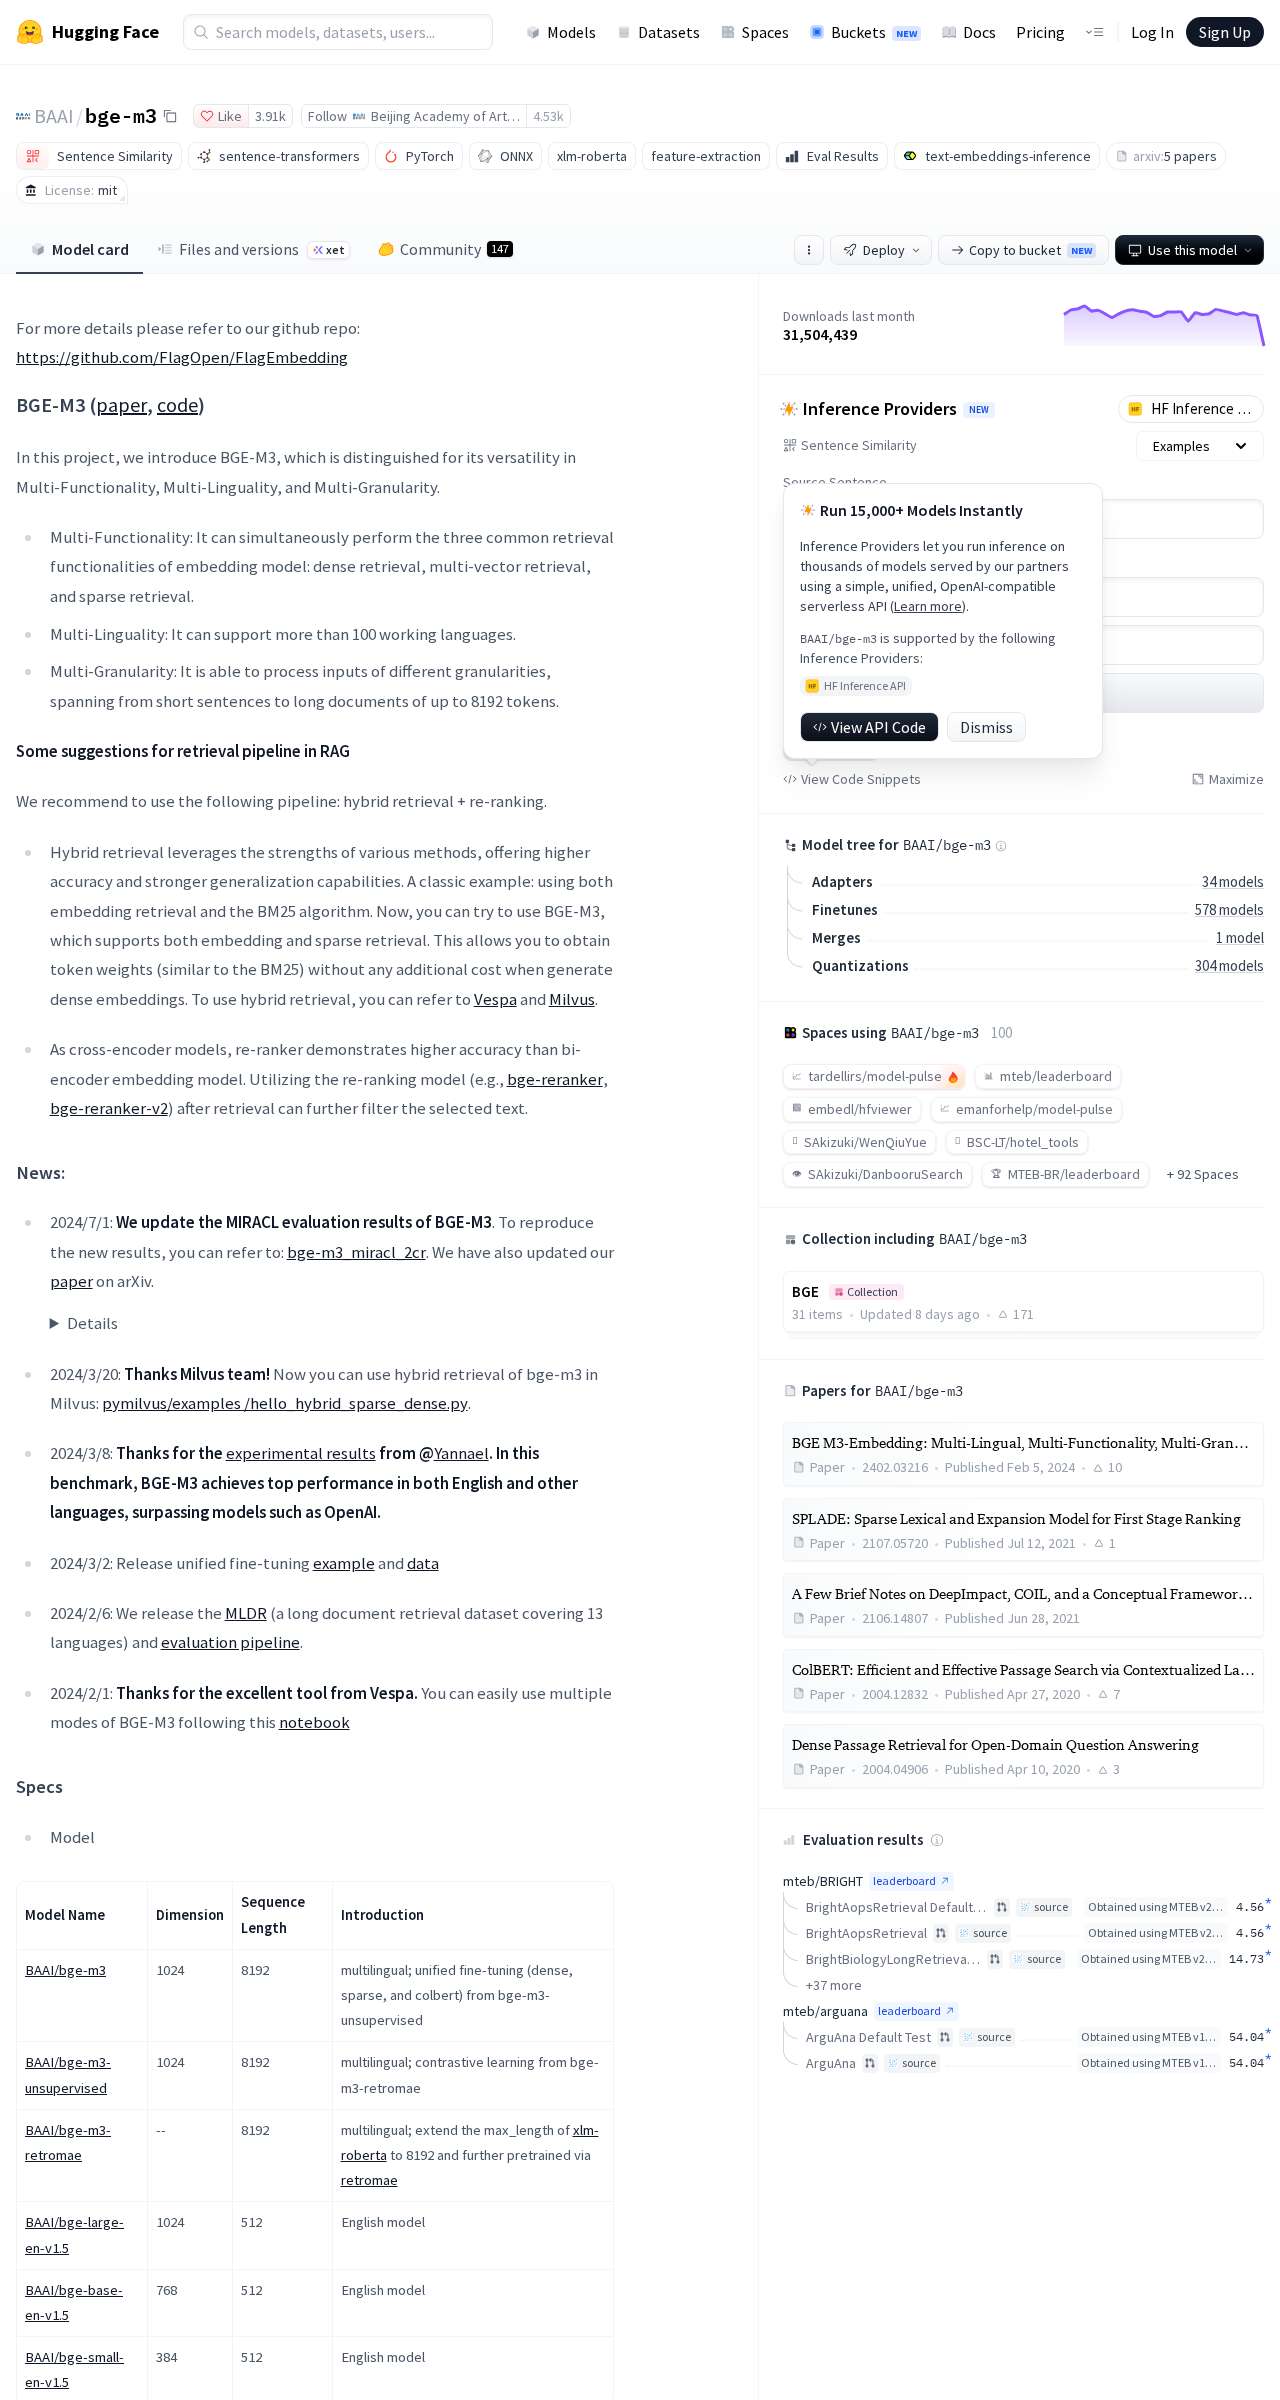
Multilingual embedding model that does dense, sparse and multi-vector retrieval in one model (BAAI).
Website captured Oct 19
Lightweight, fast chunking library (Python and TypeScript) for splitting text before embedding.
Website captured Oct 19
Open-source search infrastructure for AI: embed, store and query documents for retrieval.
Website captured Oct 19
Disclosure: the operator of shipping.buzz is a Qdrant Star Ambassador. No manual overrides apply to vector databases.
Pulls up-to-date, version-specific library docs and code examples into a coding agent's prompt, via MCP.
Prepend chunk-specific context before embedding and BM25 indexing. Anthropic measured 49% fewer failed retrievals, and 67% fewer with reranking.

Self-hostable crawler that turns any website into clean, LLM-ready Markdown.
Website captured Oct 19
Parses PDFs, Office files and scans into clean, structured documents ready for chunking and retrieval.
Website captured Oct 19
Keep what matters outside the window across turns and sessions, and bring it back when needed.
Local Markdown knowledge base that AI assistants read and write through MCP, so you stop re-explaining projects.
Website captured Oct 19
Git-backed issue tracker built as long-term memory for coding agents.
Website captured Oct 19
Captures what a coding agent does in a session, compresses it with AI and injects the relevant parts next session.
Website captured Oct 19
Open-source memory platform that turns data into a queryable knowledge graph plus vectors for agents.
Website captured Oct 19
Treat files as unlimited, persistent memory: write big observations to disk and keep only paths in context; recite a todo.md to keep goals in focus.
Builds real-time, temporal knowledge graphs from agent interactions, for memory you can query (Zep).
Website captured Oct 19

LangChain's utilities for extracting, managing and retrieving long-term agent memory.
Website captured Oct 19
Give agents actions and live data through tools: MCP servers, SDKs, registries and tool design.
Anthropic's public repository of Agent Skills: instruction folders an agent loads only when a task needs them.
Gives coding agents Chrome DevTools: inspect pages, debug and trace performance.
Website captured Oct 19
Expose MCP tools as code the agent calls from a sandbox, so only the definitions and results it needs enter context.
1,000+ app toolkits with auth, tool search and a sandbox, exposed to agents as tools or MCP.
Website captured Oct 19
MCP server that gives Claude terminal control, file search and diff-based file editing.
Website captured Oct 19
The high-level, Pythonic way to build MCP servers and clients.
Website captured Oct 19
GitHub's official MCP server: repos, issues, pull requests and Actions as agent tools.
Fit more signal into fewer tokens: compaction, summarization, token-efficient formats, repo packers, caching.
The finite attention an LLM spends across its context; every new token draws it down, so context must be curated.
CLI that converts a codebase into one prompt with a source tree, templates and token counting.
Website captured Oct 19
When a conversation nears the window limit, summarize it and restart a fresh window with the summary.
Automatically clearing stale tool calls and results from the context as it nears its limit (a Claude Developer Platform feature).
Turns any GitHub repo into a prompt-friendly text digest (swap 'hub' for 'ingest' in the URL).
Website captured Oct 19
The share of prompt tokens served from the model's key-value cache; higher means lower latency and cost.
Keep the prompt prefix stable and the context append-only so cached tokens get reused.
Split work across agents with clean, isolated contexts: agent frameworks, sub-agents, handoffs, workflows.
Google's code-first toolkit for building, evaluating and deploying agents (Python, with a JS SDK).
Website captured Oct 19
Framework and runtime for building, running and managing multi-agent systems.
Website captured Oct 19
TypeScript toolkit for AI apps and agents: tool calling, streaming and structured output across providers.
Website captured Oct 19
A programming language for agents: typed prompt functions with schema-aligned parsing of model output.
Website captured Oct 19
Build agents on Claude Code's harness from code: tools, sub-agents, context management and permissions.
Website captured Oct 19
The set of strategies for curating and maintaining the optimal set of tokens during LLM inference, including everything that lands in context outside the prompt.
Framework for orchestrating role-playing, autonomous agents that collaborate on tasks.
Website captured Oct 19
See what went into the context and whether it worked: tracing, evals, regression tests, token and cost tracking.
AI observability and evaluation: traces, evals and datasets built on OpenTelemetry.
Website captured Oct 19
Evals and observability platform (closed source), measured here through its official SDKs.
Website captured Oct 19
When new information or tools in the context conflict with other information already there.
When superfluous content in the context is used by the model to produce a low-quality response.
When context grows so long that the model over-focuses on it and neglects what it learned in training.
When a hallucination or other error makes it into the context and keeps getting referenced.
The drop in a model's ability to recall and use information as the number of tokens in its context grows.